Tiering Meaning: How Storage & Service Tiers Work
Tiering is a practical way to organize resources by importance, performance, cost, access speed, or level of service. The idea appears across technology, cloud computing, data storage, customer support, software subscriptions, networking, and business services. Instead of treating every workload, customer, file, or service request the same way, organizations divide them into clearly defined levels called tiers. Each tier receives a different combination of features, performance, availability, price, or support. This structure helps companies spend money where it creates the most value while avoiding unnecessary costs on lower-priority needs. Understanding the meaning of tiering is especially useful today because businesses manage larger data volumes, more cloud services, and increasingly complex customer expectations.
What Does Tiering Mean?
Tiering means dividing something into multiple levels according to a defined set of criteria. These levels are usually arranged from higher to lower based on factors such as performance, priority, cost, accessibility, reliability, or features. In technology, tiering may determine where data is stored, how quickly applications receive resources, or which customers receive advanced service options. In business, a company might offer basic, professional, and enterprise service tiers with different prices and capabilities. The purpose is not simply to create categories but to match resources more closely to actual needs. When designed well, tiering can improve efficiency, control expenses, and make complex products or systems easier to manage.
A tier is essentially one level inside a larger hierarchy. Tier 1 often represents the highest-performing or most important level, although naming conventions can vary between organizations. Some systems instead use labels such as premium, standard, and basic or hot, warm, and cold. The names matter less than the differences between the levels. Each tier should have clearly defined characteristics so users and administrators understand what they are receiving. For example, a premium service tier might offer faster response times, while a lower-cost tier might provide fewer features. Clear tier definitions prevent confusion and help organizations apply rules consistently across customers, systems, and internal operations.
Tiering is useful because not every resource requires the same treatment. A database supporting real-time financial transactions may need high-speed storage and strong availability, while old backup files may not need immediate access. Similarly, a critical customer issue may deserve a faster support response than a general informational question. Without tiers, organizations may overspend by giving every workload the most expensive resources available. The opposite problem can also occur when important systems receive insufficient capacity or service. Tiering creates a structured middle ground where resources are matched to business importance. This makes infrastructure, services, and budgets easier to prioritize while maintaining an appropriate level of performance.
The criteria used to create tiers depend on the environment. Storage tiering may consider data access frequency, latency requirements, capacity, and storage cost. Service tiering may focus on features, response times, support access, account limits, or pricing. Network tiering may prioritize important traffic, while application tiers may separate presentation, business logic, and data processing functions. Even cybersecurity teams can use tiers when classifying information or systems according to sensitivity. Because tiering is flexible, the same basic principle can solve very different problems. The key is defining measurable differences between levels rather than creating labels that do not meaningfully influence how resources or services are delivered.
Modern cloud platforms have made tiering more visible because customers can often choose between several performance and pricing options. Storage providers may offer classes designed for frequently accessed data, occasional access, backups, and long-term archives. Software companies commonly present multiple subscription tiers to serve individuals, small businesses, and large enterprises. Support providers may similarly offer standard and premium response levels. These examples reflect the same underlying idea: customers should not have to pay for capabilities they do not need. At the same time, organizations need enough flexibility to move between tiers as requirements change. Effective tiering therefore combines classification, cost control, performance management, and adaptability.
How Storage Tiering Works
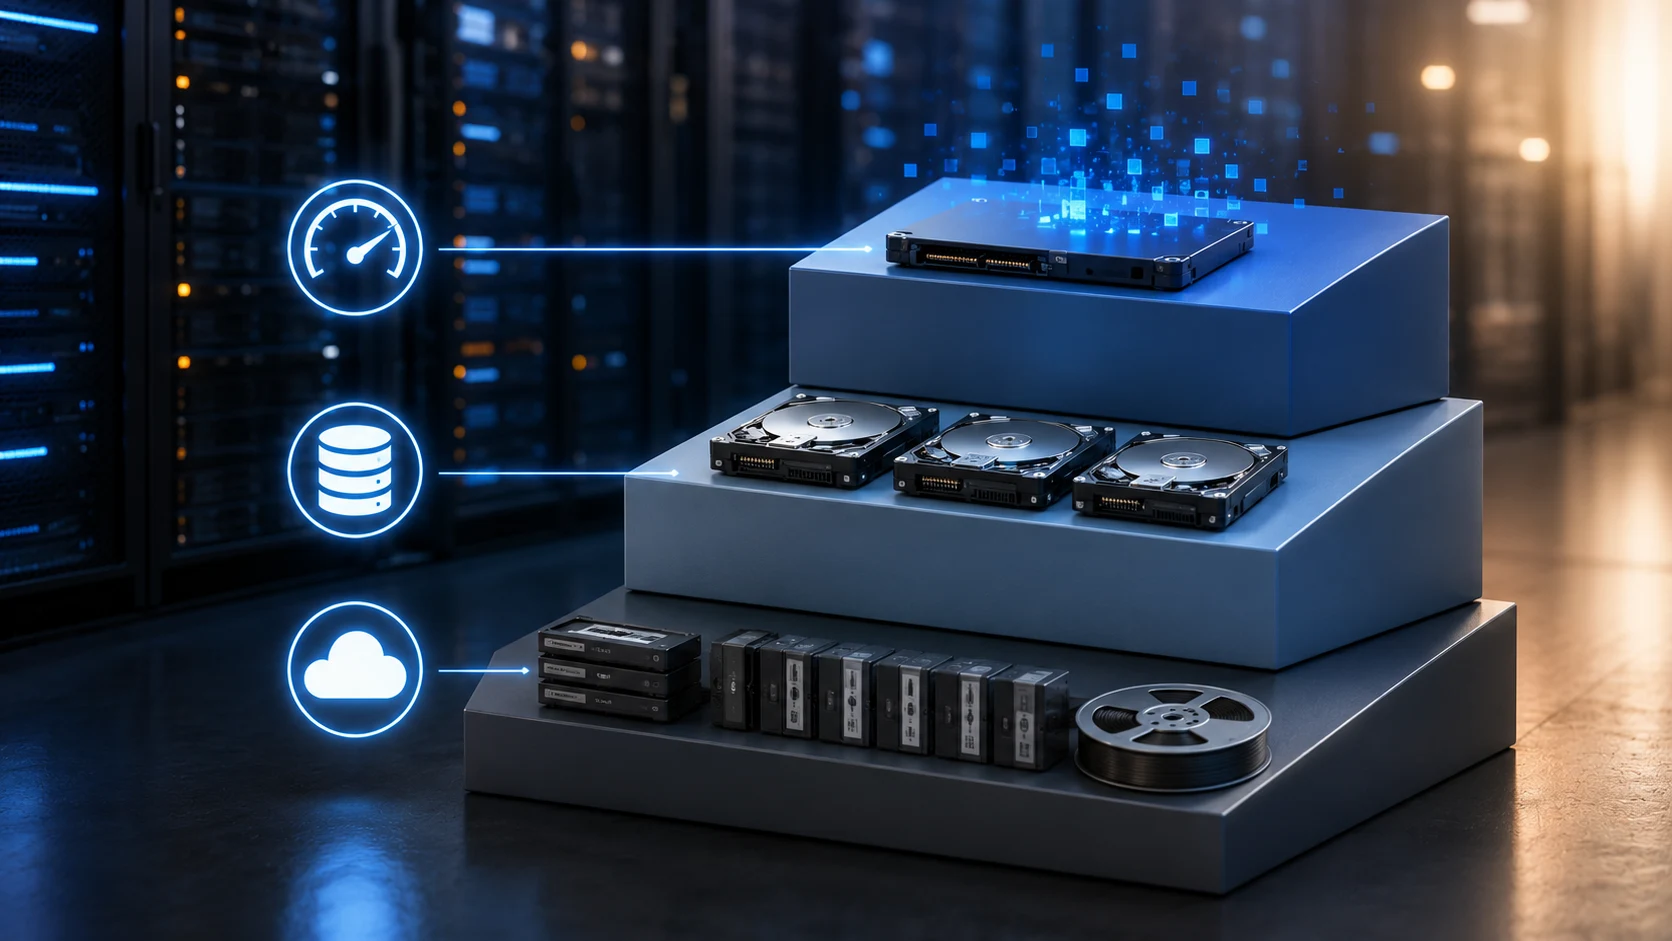
Storage tiering is the practice of placing data on different types or classes of storage according to how frequently the information is accessed and how quickly it needs to be retrieved. High-priority data may reside on fast solid-state storage, while less frequently used information can move to lower-cost capacity-oriented systems. The goal is to balance performance and expense rather than storing everything on the fastest technology available. High-performance storage usually costs more per unit of capacity, making it inefficient for inactive information. By contrast, inexpensive archival storage may be too slow for business-critical applications. Storage tiering matches each data set with an appropriate combination of speed, availability, capacity, and cost.
A typical storage environment may contain several performance levels. The highest tier may use high-speed flash storage for databases, transactional applications, virtualization, or other latency-sensitive workloads. A middle tier might store general business files and applications that need reliable performance without the highest possible speed. Lower tiers may contain backups, historical records, logs, and archive data that employees access infrequently. Some environments use disk, object storage, tape, or low-cost cloud storage for these purposes. The specific technologies continue to change, but the tiering principle remains consistent. Frequently accessed or mission-critical information receives faster resources, while inactive data moves toward more economical storage.
Storage tiering can be managed manually or automatically. In a manual approach, administrators decide which data belongs in each storage tier and move it according to established policies. This can work for small environments but becomes difficult when organizations manage terabytes or petabytes of rapidly changing information. Automated storage tiering uses software to monitor usage patterns and move data based on predefined rules. Frequently accessed files may automatically move to a faster tier, while inactive files migrate toward lower-cost storage. Automation reduces administrative work and allows the storage environment to respond continuously to changing access patterns. However, policies still require careful design because incorrect rules can move important data to inappropriate locations.
Data lifecycle management often works closely with storage tiering. Information typically changes in value and usage over time. A newly created project file may be accessed frequently during active work, but months later it may only need to be retained for reference. Instead of keeping the file permanently on premium storage, lifecycle rules can gradually move it to less expensive tiers. Eventually, the information may enter an archive tier or be deleted according to retention policies. This approach connects storage decisions with the natural life cycle of information. Organizations can therefore reduce infrastructure costs while preserving the records they need for business, legal, security, or compliance purposes.
Cloud storage has made tiering especially accessible because organizations can select storage classes without purchasing different physical hardware systems. A cloud provider may offer high-performance storage for active workloads and progressively cheaper classes for data accessed less frequently. The lower-cost options may introduce longer retrieval times or additional fees when information is accessed. Businesses therefore need to understand their data patterns before selecting a storage class. Moving the wrong information into an archive tier could create delays or unexpected retrieval expenses. Successful cloud storage tiering considers access frequency, recovery requirements, data retention, performance expectations, and total cost rather than focusing only on the advertised storage price.
Hot, Warm, and Cold Storage Tiers Explained
Hot storage is designed for information that users or applications access frequently and often need quickly. It typically prioritizes low latency, high input and output performance, and immediate availability. Active databases, customer-facing applications, frequently edited documents, and real-time analytics workloads may all benefit from hot storage. Because high performance requires more capable infrastructure, hot storage generally carries a higher cost than lower tiers. Organizations should therefore avoid keeping inactive files in this tier simply because it is convenient. Effective data classification helps determine which workloads genuinely require premium performance. When hot storage is reserved for active information, businesses can improve application responsiveness without unnecessarily increasing overall storage expenses.
Warm storage occupies the middle ground between high-performance hot storage and long-term cold storage. It is often used for information that is still valuable and may need to be accessed periodically but does not require the fastest possible response. Examples can include older project documents, reporting data, recent backups, and historical application records. Warm storage generally offers lower costs while maintaining reasonably convenient retrieval. This makes it useful for data that remains operationally relevant but no longer deserves premium infrastructure. Organizations may move information automatically from hot to warm storage after a defined period of inactivity. Such policies can reduce costs gradually without making moderately important information difficult to retrieve.
Cold storage is intended for information that is rarely accessed but still needs to be retained. Long-term backups, archived documents, historical records, compliance data, and old media files are common candidates. Cold storage usually focuses on capacity and affordability rather than immediate performance. Retrieving information may take longer, and some services charge additional fees when archived data is restored. These tradeoffs are acceptable when users rarely need the information. Cold storage can create significant savings for organizations that accumulate large volumes of inactive data. However, businesses should carefully define recovery expectations because storing critical disaster-recovery information in a very slow archive tier may conflict with required recovery time objectives.
Some environments include an even deeper archival tier for information that may remain untouched for years. This tier can offer very low storage costs but significantly longer retrieval times. Organizations commonly use it for regulatory records, historical backups, research archives, or information that must be preserved even though routine business operations no longer depend on it. Deep archive storage works best when retention needs are predictable. Users should understand that retrieving the data may require planning rather than immediate access. Policies should also verify data integrity and retention requirements over long periods. Cheap storage alone is not enough if the organization cannot reliably locate, restore, and interpret archived information when it is eventually needed.
The distinction between hot, warm, and cold data should not be viewed as permanent. Information can move between tiers as business needs change. A historical dataset sitting in cold storage might suddenly become valuable for an analytics project and need to return to a faster tier. Similarly, an active project may eventually become inactive and move downward. Automated lifecycle policies make these transitions easier by evaluating factors such as access frequency, age, and business classification. Organizations should periodically test their assumptions because data usage patterns can change. Effective tiering therefore works as a dynamic system rather than a one-time filing decision, continuously balancing performance, availability, and cost.
What Is Automated Storage Tiering?
Automated storage tiering uses software to analyze data activity and move information between storage levels without requiring administrators to manage every transfer manually. The system may observe how frequently files or data blocks are accessed, how recently they were used, and what performance they require. Based on configured policies, active information can move toward faster storage while inactive information moves toward cheaper capacity. This process helps organizations use expensive high-performance infrastructure more efficiently. Automation becomes particularly valuable in large environments where millions of files and changing workloads make manual classification impractical. The technology allows storage placement to adjust continuously as application behavior and user activity change.
Some automated tiering systems operate at the file level, while others work with smaller blocks of data. File-level tiering moves entire files between different storage systems or classes. Block-level tiering can identify frequently accessed portions of a larger dataset and place those blocks on faster infrastructure. This level of granularity may improve performance without requiring the entire dataset to occupy expensive storage. Cloud lifecycle policies often work differently by applying rules according to object age, access patterns, tags, or other metadata. Each method has advantages depending on workload characteristics. Organizations should understand how their tiering technology identifies activity because the decision-making process influences both performance and cost.
Policies form the foundation of automated tiering. Administrators may create rules stating that files not accessed for ninety days should move from a high-performance tier to a lower-cost storage class. Another rule might archive backups after a year or permanently delete temporary information after a specified retention period. More advanced systems can consider performance metrics instead of relying entirely on file age. Policies should reflect business requirements rather than arbitrary timelines. An old legal document may still require fast access, while a large newly created backup may immediately qualify for inexpensive storage. Combining metadata, business classification, and usage information generally produces more reliable tiering decisions.
Automation provides significant financial advantages because it reduces the amount of premium storage organizations need to purchase. Instead of manually identifying inactive information, systems can continually reclaim high-performance capacity by moving low-priority data elsewhere. This can postpone hardware upgrades and reduce cloud storage spending. Administrators also save time because they no longer have to track individual files or datasets manually. However, automation introduces its own management requirements. Poorly configured rules can increase retrieval charges, reduce application performance, or move sensitive information into inappropriate environments. Organizations should monitor results and adjust policies according to observed behavior rather than assuming automated decisions will always remain optimal.
Successful automated tiering depends on visibility and testing. Teams should understand where information is located, why it moved, and what impact the move has on application performance. Dashboards can help administrators monitor storage capacity, access patterns, tier transitions, and retrieval activity. Before applying new policies broadly, organizations may test them against representative datasets. Recovery procedures should also be verified because archived information still needs to be usable when requested. As storage environments become more distributed across on-premises systems and multiple cloud platforms, automation can simplify management considerably. The best results come when automated placement supports clearly defined performance, retention, security, and financial objectives.
What Is Service Tiering?
Service tiering divides a product or service into different levels based on features, availability, support, performance, usage limits, or price. Customers can then select the level that best matches their needs and budget. Software companies commonly use service tiers such as free, basic, professional, business, and enterprise. Telecommunications providers, cloud platforms, financial services, managed IT providers, and customer support organizations also use tiered service models. The highest tier usually offers greater capability, customization, or priority treatment, while lower tiers provide essential features at a lower cost. This structure gives providers a way to serve different customer groups without designing an entirely separate product for each one.
Pricing tiers are one of the most visible examples of service tiering. A software platform may offer an entry-level plan for individual users, a professional plan for growing teams, and an enterprise tier for large organizations. Each level can include different numbers of users, storage allowances, integrations, administrative controls, analytics, or security features. Customers can compare these options and decide whether additional functionality justifies the higher price. Effective pricing tiers create meaningful differences without making the structure unnecessarily confusing. Too many tiers can overwhelm buyers, while poorly defined tiers can make customers uncertain about which plan they need. Clear value progression is therefore an important part of tiered service design.
Support services frequently use tiers as well. Standard support might provide assistance during normal business hours, while premium support could include twenty-four-hour availability, shorter response targets, dedicated account contacts, or specialized technical expertise. Critical enterprise customers may purchase the highest support tier because downtime can create substantial financial consequences. Smaller customers may prefer a lower-cost option because occasional delays are acceptable. Support tiering allows service providers to allocate skilled personnel according to customer requirements. However, organizations should understand exactly what response and resolution commitments are included. A faster initial response does not necessarily guarantee that a complex technical problem will be solved immediately.
Service tiers can also define performance and availability. Cloud platforms may offer different computing or database configurations according to speed, redundancy, storage capacity, and service-level targets. A premium tier could provide higher availability or additional geographic redundancy, while a basic tier may use fewer resources. Businesses should choose according to the importance of the workload rather than automatically selecting the highest level. Internal systems used occasionally may not require the same reliability as customer-facing applications generating revenue around the clock. Matching applications with suitable service tiers helps organizations balance resilience and spending. As with storage tiering, the goal is to apply premium resources where they create measurable value.
Customers should periodically review their service tiers because requirements change over time. A growing company may outgrow a basic software plan and need stronger security or administrative controls. Another organization may discover that it pays for enterprise features employees never use. Usage analytics can help determine whether upgrading or downgrading would create better value. Contract renewal periods provide a natural opportunity to conduct these reviews. Businesses should also watch for changes in vendor packaging because features sometimes move between tiers. Effective service tier management is therefore an ongoing process of comparing business needs, actual usage, contractual commitments, and cost rather than making a single permanent selection.
Tier 1, Tier 2, and Tier 3 Services Explained
Tier 1 generally refers to the first or highest-priority level in many service structures, although specific meanings vary by organization. In technical support, Tier 1 often serves as the initial contact point for customers and handles common or straightforward issues. These support agents may resolve password resets, basic configuration questions, account problems, or known errors. More complicated cases are escalated when additional expertise is required. In infrastructure contexts, Tier 1 can instead represent the highest performance or availability category. Because numbering conventions differ, businesses should never assume that Tier 1 always means exactly the same thing. The service definition and associated commitments are more important than the label itself.
Tier 2 support typically handles issues that require greater technical knowledge than front-line teams possess. These specialists may investigate application behavior, reproduce errors, analyze logs, troubleshoot integrations, or resolve advanced configuration problems. They often receive escalations from Tier 1 after common solutions have been attempted. Having multiple support levels prevents highly specialized engineers from spending most of their time on routine requests. At the same time, customers can receive faster assistance for simple problems because front-line teams are designed to handle high volumes efficiently. Clear escalation procedures are essential because customers become frustrated when cases repeatedly move between teams without progress. Good tiering should improve problem resolution rather than create bureaucratic barriers.
Tier 3 usually represents highly specialized expertise in a traditional technical support hierarchy. Engineers, developers, product specialists, or senior infrastructure experts may work at this level. They handle complex incidents that require deep knowledge of software architecture or underlying systems. A Tier 3 investigation might involve analyzing unusual application failures, correcting defects, developing patches, or diagnosing interactions between multiple technologies. These resources are expensive and limited, so organizations typically reserve them for cases that cannot be solved at earlier levels. A well-designed support structure ensures that enough diagnostic information accompanies an escalation. This prevents senior specialists from repeating basic troubleshooting that previous teams should already have completed.
The same tier numbering can appear in other service environments. Data centers, networks, vendors, suppliers, cybersecurity operations, and business continuity programs may use numerical tiers to represent different levels of capability or importance. A company might classify critical applications as Tier 1 because they require the strongest recovery resources. Less essential systems could fall into Tier 2 or Tier 3 with progressively longer acceptable recovery times. Supplier management can follow a similar structure, with strategically important vendors receiving greater oversight. The meaning therefore depends heavily on context. Whenever organizations introduce numbered tiers, they should document the criteria clearly so employees, customers, and partners interpret the classification consistently.
Tiered support models work best when movement between levels is efficient. Users should not need to understand the internal organization before receiving assistance. The service provider should gather relevant information, route the issue correctly, and maintain context during escalation. Automation can help classify requests according to product, severity, customer type, and issue category. Knowledge bases can also allow Tier 1 agents to solve a wider range of common problems. Metrics such as first-contact resolution, escalation rates, response time, and customer satisfaction can reveal whether the tier structure is functioning effectively. Ultimately, service tiering should make expertise easier to access rather than simply adding additional layers between customers and solutions.
Benefits and Challenges of Tiering
One of the strongest benefits of tiering is cost optimization. Organizations can reserve premium resources for workloads, information, or customers that genuinely require them. Storage tiering prevents inactive data from consuming expensive high-performance capacity. Service tiering allows customers to purchase functionality appropriate to their needs instead of paying for a single oversized package. Support tiering directs highly specialized employees toward difficult problems while routine requests remain with front-line teams. These efficiencies can create significant savings at scale. The principle is simple: expensive resources should be used where their additional value can be justified. Tiering provides the structure necessary to apply that principle consistently across large and complicated environments.
Performance management is another important advantage. Critical applications can receive faster storage, better computing resources, greater network priority, or higher service availability. Less important workloads can operate on more economical infrastructure without affecting essential systems. This distinction becomes increasingly valuable as businesses manage hundreds of applications and large quantities of information. Attempting to maximize the performance of everything would create unnecessary expense. Tiering instead establishes clear priorities. When administrators know which workloads belong to the highest tier, they can make better decisions during capacity shortages or incidents. This alignment between technical performance and business importance improves both reliability and financial efficiency.
Tiering can also simplify decision-making for customers. Instead of configuring every individual product feature, buyers can select from predefined service packages designed around common needs. A small business may choose a standard tier, while a large enterprise can select advanced security and administrative capabilities. Clear packages reduce purchasing complexity and help customers compare costs. Internally, tiering provides similar benefits by giving employees common categories for discussing systems and priorities. Teams can quickly understand that a Tier 1 application requires greater protection than a Tier 3 internal tool. However, these benefits depend on definitions remaining consistent. Too many overlapping or poorly documented tiers can create more confusion rather than less.
One challenge is deciding where boundaries between tiers should exist. Data usage does not always fit neatly into hot, warm, or cold categories, and customer needs may fall between available service plans. An application might be highly important during certain periods and relatively inactive during others. Fixed classifications can therefore become outdated. Organizations should build enough flexibility to reclassify workloads as conditions change. Automated systems can help when decisions depend on measurable activity, but human judgment remains important for business context. Periodic reviews prevent old classifications from becoming permanent simply because nobody revisits them. Effective tiering should adapt as technology, demand, and organizational priorities evolve.
Another challenge is understanding the hidden tradeoffs associated with lower tiers. Cheaper storage may introduce retrieval delays or additional access charges. Lower service tiers may omit security controls, integrations, support, or performance guarantees that a business later discovers it needs. Selecting the lowest-cost option without analyzing these differences can create operational problems. The highest tier is not automatically the correct answer either. Organizations should evaluate total cost, risk, performance, availability, and actual usage together. When tiering decisions reflect measurable business requirements, they can deliver excellent efficiency. When decisions are based purely on labels or advertised pricing, the tier structure may create unexpected expense or service limitations.
How to Choose the Right Storage or Service Tier
Choosing an appropriate tier begins with understanding the workload or business requirement rather than comparing prices first. For storage, organizations should examine how frequently data is accessed, how quickly it must be retrieved, and how damaging delays would be. For service plans, businesses should identify the features, capacity, support, and security capabilities employees genuinely need. Critical requirements should be separated from features that would simply be convenient. This prevents organizations from paying premium prices for unnecessary capabilities. At the same time, it reduces the risk of choosing a lower tier that cannot support essential operations. A requirement-driven approach creates a more reliable foundation for tier selection than cost alone.
Access frequency is particularly important for storage decisions. Data requested continuously by applications should usually remain in faster storage, while information accessed only a few times each year may belong in an archive tier. Organizations should analyze real usage data whenever possible because employees may overestimate how often old information is needed. Historical access patterns can reveal opportunities to move large volumes of inactive information to lower-cost storage. However, access frequency should not be the only factor. Recovery objectives, compliance requirements, legal obligations, and business importance may justify keeping certain information more accessible. The best storage tier balances how often information is used with how quickly it must become available when needed.
Total cost should include more than the monthly or per-gigabyte price displayed by the provider. Lower-cost storage classes may charge additional fees for data retrieval, transactions, or early deletion. A service tier may appear inexpensive until add-ons are required for security, support, analytics, or additional users. Organizations should estimate realistic usage and calculate costs across the expected lifecycle. Comparing several scenarios can reveal how expenses change when consumption grows. Businesses should also consider switching costs because migrating data or retraining employees may make future changes expensive. Total cost of ownership provides a much more accurate picture than simply choosing whichever tier has the lowest advertised rate.
Security requirements can strongly influence tier selection. Some software vendors reserve advanced identity management, audit logging, encryption controls, or compliance capabilities for higher service tiers. Businesses handling sensitive information may therefore need an enterprise plan even when they do not require its other advanced features. Storage systems may also differ in replication, availability, access-control capabilities, or geographic options. Security teams should participate in tier decisions for important applications rather than reviewing the service only after purchase. Selecting a cheaper tier and later discovering that necessary controls are unavailable can force an expensive upgrade. Incorporating security requirements early prevents price comparisons from overlooking critical risk-management capabilities.
Finally, organizations should view tier selection as reversible whenever possible. Requirements change as projects end, employee numbers fluctuate, data becomes older, and technology evolves. A workload that needs premium infrastructure today may qualify for a lower-cost tier next year. Similarly, a small software subscription may need upgrading when a business expands. Regular reviews help ensure that resources remain aligned with actual requirements. Automation can simplify these adjustments for storage and cloud services by moving resources according to policy. Contract flexibility matters for service plans because businesses should understand how easily they can upgrade, downgrade, or change usage commitments. Good tiering continuously matches resources with needs rather than locking every decision permanently in place.
Frequently Asked Questions About Tiering
What does tiering mean in simple terms?
Tiering means organizing resources, products, services, or data into different levels based on factors such as performance, price, importance, features, or access speed. Each level provides a different combination of capabilities so resources can be matched more closely to actual needs.
What is storage tiering?
Storage tiering is the practice of placing data on different storage classes according to access frequency, performance requirements, and cost. Frequently used information may stay on high-speed storage, while older or rarely accessed information can move to cheaper archival systems.
What is the difference between hot, warm, and cold storage?
Hot storage is designed for frequently accessed data that requires fast performance, while warm storage is generally used for information accessed occasionally. Cold storage is intended for rarely accessed data where lower cost is more important than immediate retrieval.
What does tiering mean in customer service?
In customer service, tiering divides support into different levels according to expertise, priority, response times, or customer plans. Basic issues may be handled by Tier 1 support, while increasingly complex problems move to more specialized Tier 2 or Tier 3 teams.
Why do businesses use tiered services?
Businesses use tiered services to offer different combinations of price, features, performance, and support for different customer needs. Tiering also helps providers allocate expensive resources more efficiently while giving customers greater control over how much service they purchase.